

If companies that build dedicated AI governance infrastructure are doing something real — creating committees, naming policies, screening for AI expertise on the board — then a natural question follows: does the market reward it?
We tested this directly. We took the forty-six companies from our early-season universe that have both AI governance tier data and public market data, matched them to one-year stock returns, and asked whether the fifteen “governed” companies — those with at least one dedicated AI body, named AI policy, skills-matrix entry, or dedicated proxy section — outperformed the rest.
While the most compelling arguments for AI governance often center on ethics, risk mitigation, regulatory compliance, and social responsibility, this article focuses specifically on the question of financial returns. The aim here is not to diminish the importance of those broader considerations, but to test whether the market currently rewards companies for building AI governance infrastructure.
The answer is no — but at forty-six companies and one year of data, it would be remarkable if it were yes. AI governance is a new field. The disclosure infrastructure barely exists. The more useful question is not whether a premium shows up in this sample, but what the sample tells us about when and how one could.
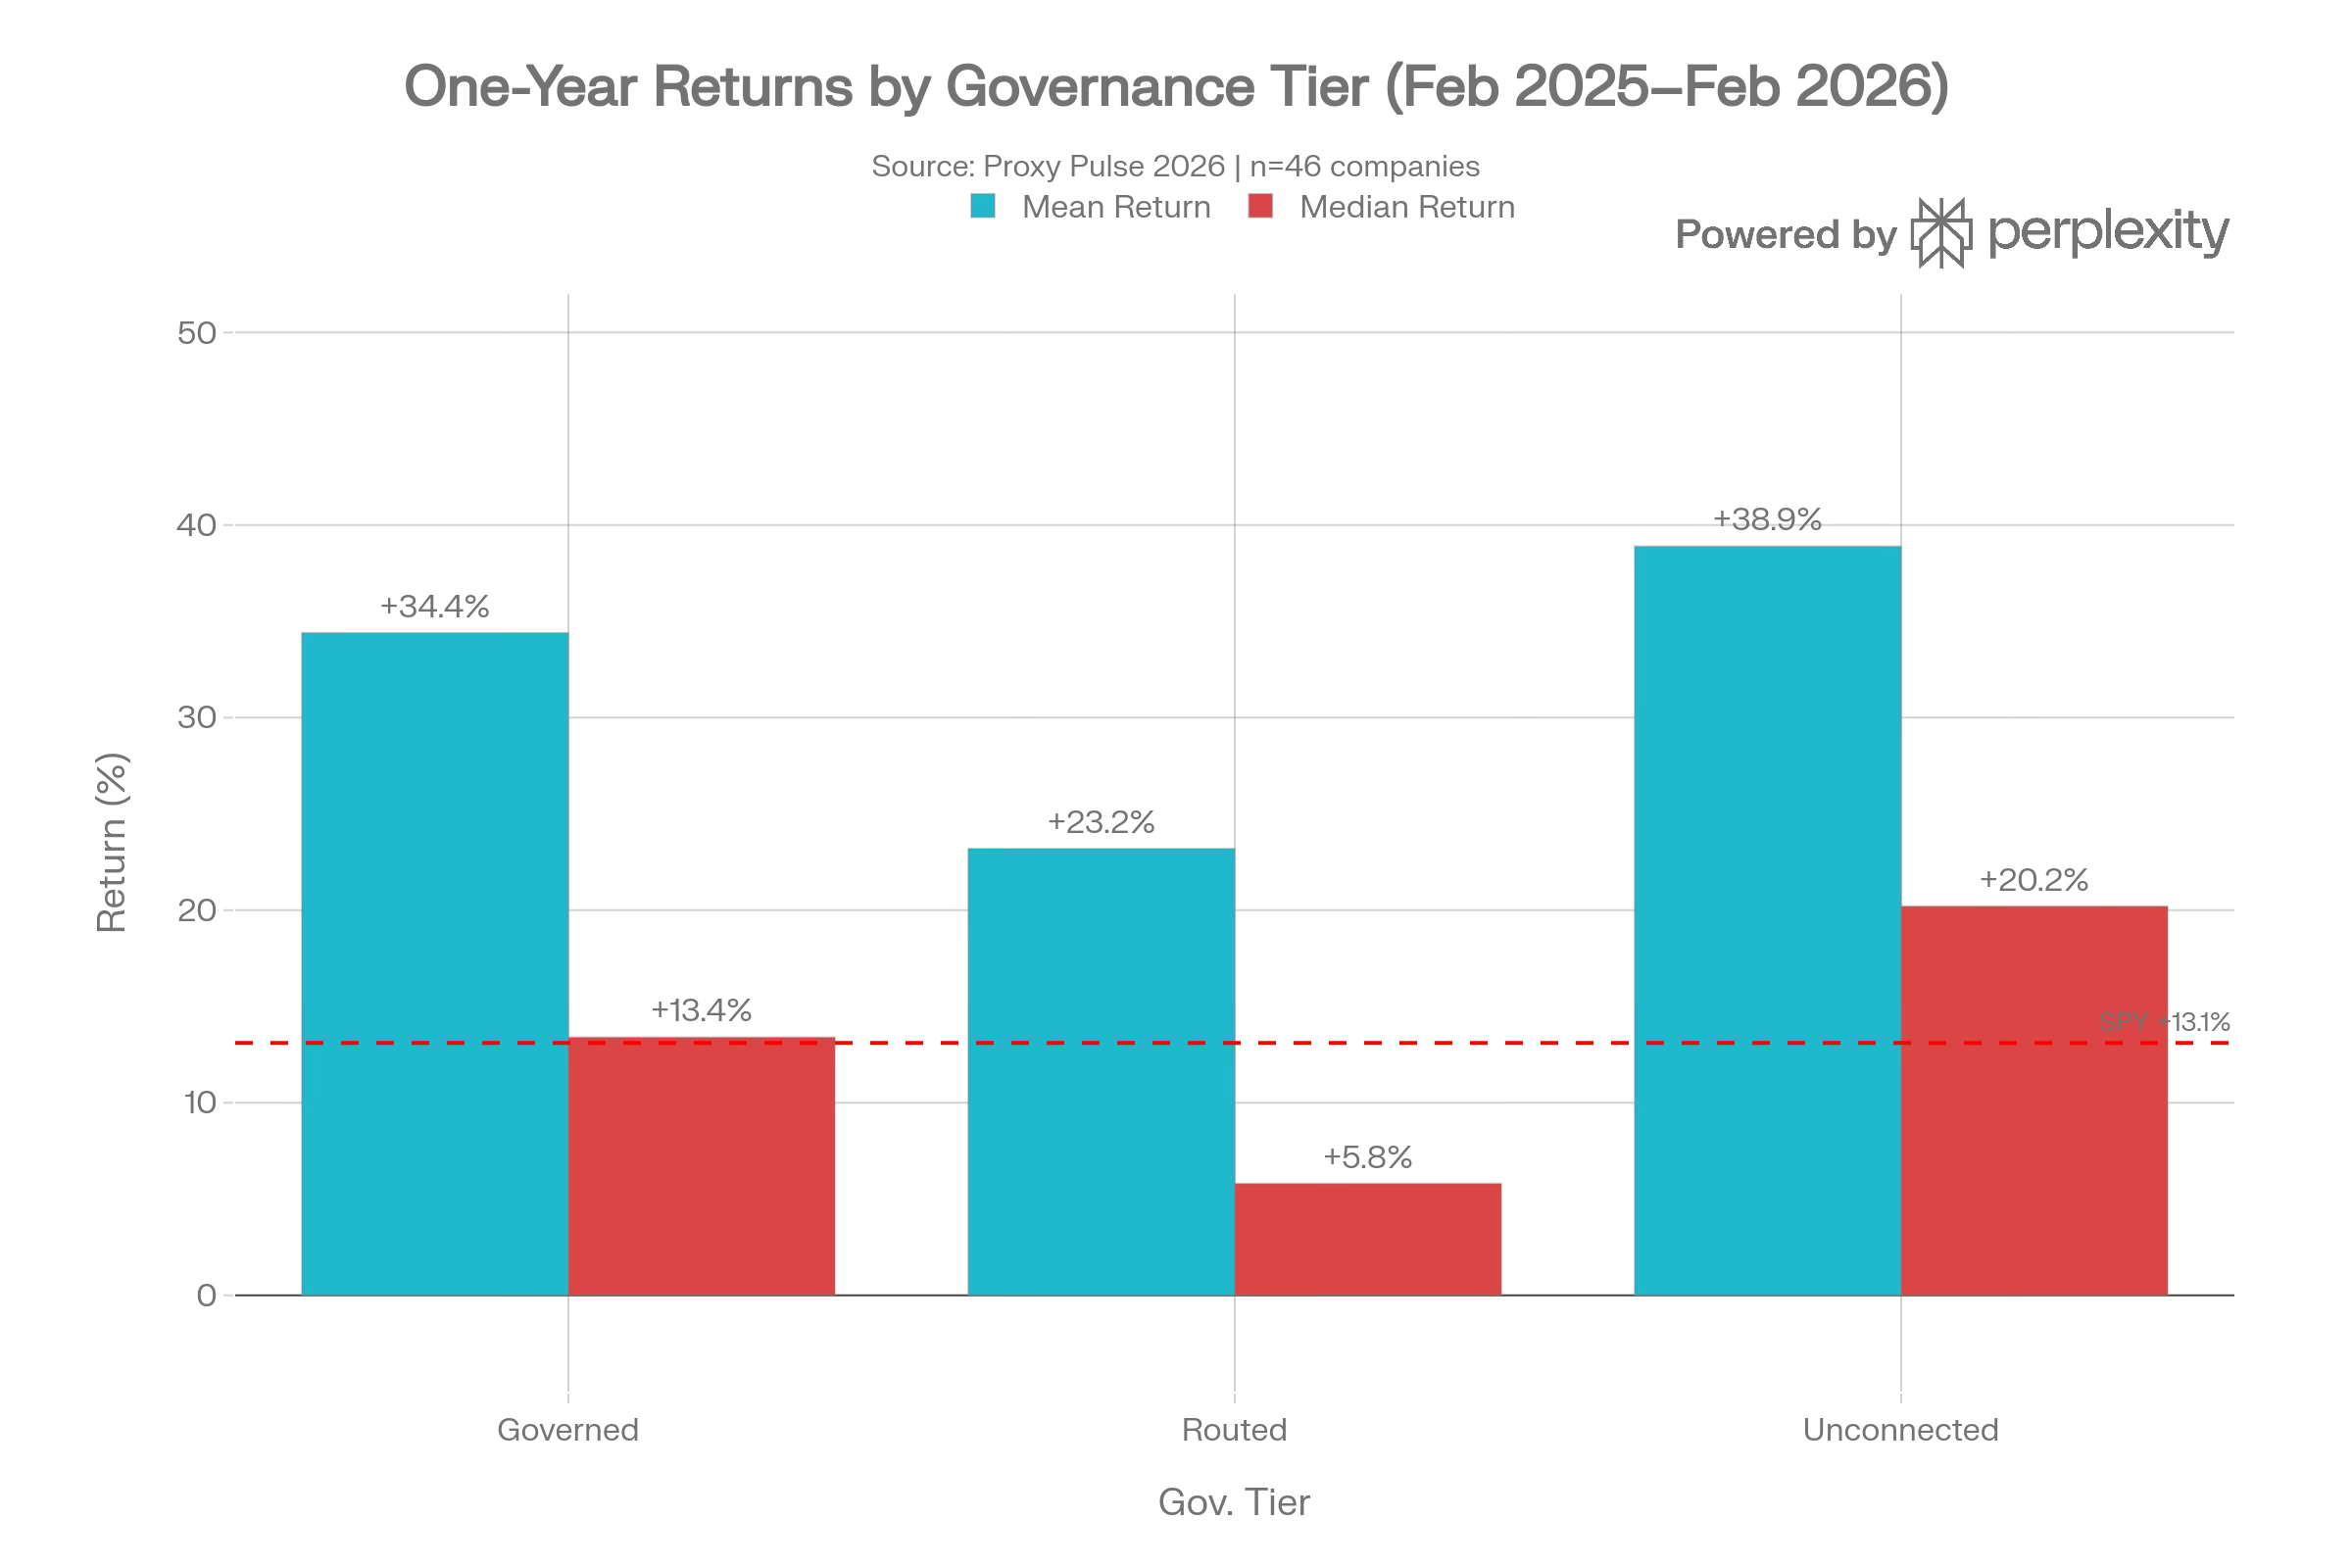
We merged three datasets: the committee-level AI governance classifications from the census (62 companies, three tiers), market capitalisation data from EDGAR filings (classified into mega, large, mid, and small cap), and twelve-month stock returns through February 14, 2026, benchmarked against the S&P 500 (SPY: +13.1%).
Forty-six companies had complete data across all three. Fifteen classified as Governed, seventeen as Routed (AI mentioned via existing committees, no dedicated infrastructure), fourteen as Unconnected (AI mentioned with no governance attachment).
What the Numbers Show
“Returns calculated using Yahoo Finance’s unadjusted Close price series [or Adj Close, as applicable], representing price appreciation only, with no dividend reinvestment. The SPY benchmark is measured on the same basis.”
These are raw returns, unadjusted for dividends, risk factors, or sector tilts. The “excess” columns subtract the SPY benchmark but do not control for size, value, momentum, or profitability exposures — so any apparent governance signal is confounded with the factor exposures of the companies in each tier. The comparison conflates the governance question with every other systematic return driver simultaneously. We report it as a descriptive baseline, not as a causal estimate.
Read the means and the story looks ambiguous. Read the medians — which strip out outlier effects — and the governed tier barely matches the benchmark. The unconnected tier, the companies where AI appears in the proxy with zero governance infrastructure, has the highest median excess return.
The statistical tests confirm the visual impression. A Kruskal-Wallis test across the three tiers produces H = 1.23, p = 0.54. A Mann-Whitney test comparing governed companies directly against unconnected companies produces p = 0.91. Spearman rank correlation between governance feature count and one-year return: ρ = 0.11, p = 0.46. None of these results approach conventional significance thresholds.
There is no AI governance premium in this sample. Given the sample size, the newness of AI governance as a disclosure category, and the absence of any standardised screening framework, this is the expected result — not a surprising one.
Why the Literature Predicts This: A History of Measuring Governance Returns
The null result is consistent with a large body of corporate governance research that has wrestled with the same question — does good governance pay? — across multiple governance domains for more than two decades. Every domain followed the same arc: early enthusiasm, methodological refinement, and eventual attenuation. Understanding that arc is essential to interpreting what our AI governance test means.
Anti-Takeover Provisions: The Original Governance Factor
The foundational study is Gompers, Ishii, and Metrick’s “Corporate Governance and Equity Prices” (*Quarterly Journal of Economics*, 2003), which constructed a governance index from twenty-four anti-takeover provisions and found that a long-short portfolio — buying well-governed firms, shorting poorly-governed ones — earned 8.5% annual excess returns through the 1990s. That result reshaped how investors thought about governance as a factor and launched two decades of governance-return research.
But the follow-up literature complicated the story substantially. Core, Guay, and Rusticus (”Does Weak Governance Cause Weak Stock Returns?”, *Journal of Finance*, 2006) re-examined the same data and found that the governance-return link weakened once markets became aware of it — the alpha disappeared in the post-publication sample. Bebchuk, Cohen, and Ferrell (”What Matters in Corporate Governance?”, *Review of Financial Studies*, 2009; working paper version circulated 2004) showed that of the original twenty-four provisions, only six — their “E-Index” — drove the association, and even those attenuated over time. By the time governance indices became common screening tools, the pricing anomaly had largely closed. Ammann, Oesch, and Schmid (*Journal of Financial Economics*, 2011) confirmed this internationally — governance correlated with firm value but not reliably with future excess returns once properly controlled for sector, size, and institutional ownership.
The anti-takeover provisions story established a pattern that would repeat across every subsequent governance factor: *initial signal → publication → market incorporation → alpha decay*. The governance features that predict returns are precisely the ones the market has not yet learned to price.
Board Diversity: The Endogeneity Problem
Board diversity research followed a similar trajectory. Carter, Simkins, and Simpson (”Corporate Governance, Board Diversity, and Firm Value”, *The Financial Review*, 2003) found a positive association between the proportion of women and minorities on the board and Tobin’s Q, concluding that diversity enhanced shareholder value. The study was widely cited by investors and regulators as evidence that board diversity pays.
Adams and Ferreira (”Women in the Boardroom and Their Impact on Governance and Performance”, *Journal of Financial Economics*, 2009) complicated this picture fundamentally. Using panel data and instrumental variable estimation, they found that while gender-diverse boards improved monitoring — higher attendance rates, more committee assignments, tougher CEO accountability — the negative value effect was concentrated in firms with fewer anti-takeover provisions — those the Gompers framework would classify as already well-governed. Over-monitoring destroyed value precisely where governance was already strong. The diversity-return relationship was not linear; it was contingent on the firm’s pre-existing governance quality.
The lesson for AI governance research is direct. A dedicated AI committee could improve oversight *and* reduce value if it adds bureaucratic friction to AI deployment decisions. The direction of the effect is not self-evident, and any empirical test must allow for the possibility that more governance infrastructure produces worse outcomes in firms that are already well-governed in other dimensions.
ESG: The Measurement Divergence Problem
The ESG-return literature is the largest body of governance-factor research — and the most contested. Friede, Busch, and Bassen (”ESG and Financial Performance: Aggregated Evidence from More than 2,000 Empirical Studies”, *Journal of Sustainable Finance & Investment*, 2015) surveyed 2,200 studies and found that roughly 90% showed a non-negative ESG-return relationship. This meta-analytic result became the empirical foundation for sustainable investing.
But the meta-analysis aggregated studies with different definitions of ESG, different return windows, and different control structures. Eccles, Ioannou, and Serafeim (”The Impact of Corporate Sustainability on Organizational Processes and Performance”, *Management Science*, 2014) found that “high sustainability” companies outperformed over the long run — but they defined sustainability by whether companies had adopted environmental and social policies by 1993, which selected for early-mover firms that may have been better-managed in general. The governance variable and the quality variable were difficult to disentangle.
The fatal blow to simple ESG-return claims came from Berg, Kölbel, and Rigobon (”Aggregate Confusion: The Divergence of ESG Ratings”, *Review of Financial Studies*, 2022), who showed that the correlation between major ESG rating providers’ scores was only 0.54 — compared to 0.99 for credit ratings. When the measurement of the governance variable is that noisy, any return relationship is attenuated toward zero almost by construction. You cannot price what you cannot consistently measure.
AI governance disclosure in 2026 is in worse shape than ESG ratings were when Berg, Kölbel, and Rigobon studied them. At least ESG had multiple competing measurement frameworks. AI governance has none. Our three-tier classification is the first systematic attempt to categorise AI governance infrastructure from proxy filings, and it is based on keyword and regex scanning, not expert assessment.
Cybersecurity Governance: The Event-Study Precedent
The governance domain most analogous to AI governance is cybersecurity oversight, which followed essentially the same emergence pattern a decade earlier: a risk category first mentioned in passing, then given committee-level attention, then the subject of investor and regulatory expectations.
Kamiya, Kang, Kim, Milidonis, and Stulz (”Risk Management, Firm Reputation, and the Impact of Successful Cyberattacks on Target Firms”, *Journal of Financial Economics*, 2021) studied the effect of cyber-attacks on firm value and found that firms with stronger risk governance experienced smaller valuation losses — but the effect was only detectable through event-study methodology around specific incidents, not through cross-sectional return comparisons. The baseline cross-section — do firms with cybersecurity committees outperform firms without them? — showed no significant relationship, just as our AI governance test finds none.
Lending, Minnick, and Schorno (”Corporate Governance, Social Responsibility, and Data Breaches”, *The Financial Review*, 2018) found that better-governed firms experienced smaller stock price declines after data breaches, but again only through event-study windows, and only when governance was measured with sufficient granularity. The crude binary — has a cybersecurity committee or does not — was not predictive.
This is the closest methodological precedent for AI governance research. The cybersecurity literature suggests that governance infrastructure creates value not in the cross-section (governed firms outperforming ungoverned firms over rolling periods) but in the event window (governed firms suffering smaller losses when adverse events occur). For AI governance, the equivalent test would be: when an AI-related controversy, regulatory action, or deployment failure occurs, do companies with dedicated AI governance infrastructure experience less damage? That test requires both AI governance data *and* a database of AI-related adverse events. Neither exists at scale today.
The Universal Pattern
Across anti-takeover provisions, board diversity, ESG, and cybersecurity governance, the same pattern holds:
1. Early-phase research finds associations (Gompers et al., Carter et al., Friede et al.) — but these are often driven by selection effects, sector concentration, or pre-existing firm quality.
2. Methodological refinement weakens the signal (Core/Guay/Rusticus, Adams/Ferreira, Berg/Kölbel/Rigobon) — once you control for endogeneity, size, sector, and measurement noise, the headline result attenuates.
3. Granular measurement reveals contingent effects (Bebchuk’s E-Index, Adams and Ferreira’s non-linear diversity effect, Kamiya et al.’s event-specific cybersecurity result) — governance features matter in specific circumstances, not uniformly.
4. Market incorporation eliminates the trading signal (the G-Index alpha decayed; ESG premiums have compressed as ESG investing scaled) — once governance becomes a screening criterion, it enters prices and stops predicting excess returns.
AI governance is at step zero: too few observations, no standardised measurement, no index provider coverage, no market awareness. A detectable premium at this stage would be the anomaly, not the null. The field that generated the G-Index took twenty years to produce reliable results — and even those attenuated once disclosed. AI governance as a proxy disclosure category is less than two years old. We have forty-six companies and twelve months. What we are testing is whether a governance factor that lacks a measurement framework, lacks an index, lacks advisory-firm coverage, and is disclosed by barely one-fifth of AI-mentioning filers shows up in unadjusted returns over a single year. The literature does not predict that it would.
What Confounds the Test
The null result is expected, but it is worth understanding *why* this test was never likely to find a signal even if one exists. Four structural limitations matter.
Sample size. Forty-six companies, fifteen of them governed, is too small for reliable inference. The Kruskal-Wallis test has limited power at these group sizes. A single outlier — Comtech Telecommunications returned +151% — can move the group mean by ten percentage points. The test needs hundreds of observations to separate a governance signal from noise, and early-season filings provide dozens.
Classification validity. Comtech is classified as “governed” on the strength of a single Technology Committee reference captured by the keyword scan. This is not a governance programme — it is a naming artefact. A manual expert review would not classify Comtech as having dedicated AI governance infrastructure. Yet in our binary system, it registers identically to Hewlett Packard Enterprise’s four-body architecture. This is not merely an outlier problem; it is a classification validity problem. The governed tier includes companies whose “governance” is an artefact of automated text matching, and the return test treats them as equivalent to companies with genuine organisational investment in AI oversight. Any signal in the data is diluted by misclassification noise before statistical tests even run.
Size confound. The governed tier has a mean market capitalisation of $282 billion, inflated by Apple ($3.5 trillion) and Disney ($200 billion). The unconnected tier averages $37 billion. The routed tier averages $11 billion. In the regression, controlling for log market cap, the feature-count coefficient is +3.2 percentage points per additional governance feature — the directional sign is positive — but R² is 0.11 and the coefficient is not significant. The size disparity means any return comparison is partly a large-cap-versus-mid-cap comparison, not a governance comparison.
Sector concentration. Nine of the fifteen governed companies are in technology. Within the technology sector specifically, governed companies returned +54.2% versus +43.2% for others — an eleven-point difference that evaporates once you note that Comtech alone contributes most of it. Within consumer sectors, governed companies (Disney, Starbucks, ABM, Lionsgate) returned -10.2% while non-governed consumer companies returned +10.9%. The governance “signal” runs in opposite directions depending on which industry you examine. This mirrors the sector-dependence problem identified in ESG-return research by Berg, Kölbel, and Rigobon (”Aggregate Confusion: The Divergence of ESG Ratings”, *Review of Financial Studies*, 2022), where they showed that ESG rating disagreement across providers substantially weakens any observed ESG-return link.
Measurement horizon. We test one-year trailing returns against governance disclosures that were filed within the past few months. The proxy disclosure is a lagging indicator of governance decisions made quarters or years earlier. The academically appropriate test would track returns *from the date of disclosure* — measuring whether the market responds to the *signal* of AI governance infrastructure, not whether governed companies happened to be in sectors that outperformed over the prior twelve months. Our test cannot distinguish between “AI governance predicts returns” and “companies in high-returning sectors are more likely to disclose AI governance.”
The Six-Month Divergence
One pattern in the data is worth noting briefly. Six-month returns show a monotonic gradient — governed median +28.4%, routed +12.8%, unconnected +10.7% — that the one-year returns do not. The arithmetic suggests this is largely a Comtech artefact: the governed tier’s mean six-month return (+39.4%) exceeds its twelve-month mean (+34.4%), implying negative first-half contribution, while the unconnected tier’s twelve-month outperformance is almost entirely a first-half phenomenon consistent with a front-loaded momentum spike in one small-cap stock. The same sample-size and classification-validity limitations that make the one-year comparison uninformative apply here with equal force. We note the gradient for longitudinal tracking; it does not change the null result.
The Measurement Problem
The deeper issue is not about returns. It is about whether governance infrastructure, as measured by proxy disclosure, maps onto governance *quality*.
Gillan, Koch, and Starks (”Firms and Social Responsibility: A Review of ESG and CSR Research in Corporate Finance”, *Journal of Financial Economics*, 2021) documented a fundamental challenge in all governance-factor research: the features that are easy to measure (board structure, committee composition, policy adoption) are not necessarily the features that create value. A company can name a Responsible AI Committee and staff it with people who have no AI expertise. Another company can run a rigorous internal AI review process that never appears in a proxy filing.
Our census captures *disclosure*, not *quality*. Hewlett Packard Enterprise’s four-body AI governance architecture may represent genuine organisational capability — or it may represent an investor-relations response to disclosure expectations. Comtech’s Technology Committee reference is categorically different from HPE’s infrastructure, yet both register as “governed” in our binary classification. The earlier articles in this series showed that the proxy disclosure gap (what companies say about AI governance) and the infrastructure gap (what governance structures actually exist) reinforce each other. The return test adds a third gap: the distance between governance disclosure and governance *effectiveness*.
This is the same conceptual problem that Larcker, Richardson, and Tuna identified in “Corporate Governance, Accounting Outcomes, and Organizational Performance” (*The Accounting Review*, 2007): governance indices aggregate features that may have different, or even opposing, effects on firm value. Adding the features together into a single index obscures the variation that matters. Our three-tier classification does the same thing at a smaller scale.
What a Proper Test Would Require
If someone wanted to test the AI governance premium rigorously, the minimum design would need to address five challenges that the governance-return literature has identified over two decades of methodological refinement. Each challenge has a known solution — the difficulty is that all of them require data that does not yet exist at scale.
Sample Size and Statistical Power
At least two hundred AI-mentioning companies with governance classifications, preferably spanning two or more proxy seasons. Peak-season 2026 filings will expand the current sixty-two to several hundred. The 2027 cycle will permit year-over-year comparison.
The power constraint is not just about observation count — it is about effect size. The governance-return effects that survived peer review in the anti-takeover and board diversity literatures ran 2–5 percentage points annually once properly controlled. Detecting a 3-percentage-point annual difference between governed and ungoverned firms with 80% statistical power and conventional significance thresholds requires at minimum 150–200 firms per group, assuming return volatility typical of US equities. Our fifteen governed companies and fourteen unconnected companies give the test essentially zero power against a plausible effect of that magnitude. A non-significant result in a severely underpowered test carries no information about whether the effect exists — it tells you only that the test was not designed to find it.
Event-Study Design
The methodologically appropriate approach, drawn directly from the cybersecurity governance literature (Kamiya et al., 2021), is an event-study framework: track abnormal returns in a window around the proxy filing date, not trailing returns over an arbitrary calendar period. If the market values AI governance disclosure, the reaction should be measurable in the days and weeks following the filing — analogous to the earnings-announcement literature.
This design has two variants, and the relevant one depends on what kind of value AI governance creates.
The disclosure-response variant tests whether investor reactions to the proxy filing differ based on the quality of AI governance disclosure. The prediction is that firms revealing substantive AI governance infrastructure experience more positive (or less negative) abnormal returns in a short window (±3 to ±10 trading days) around the filing date. This is the test that the six-month gradient in our data — governed outperforming on shorter horizons — weakly suggests might work, though it is far from confirmed.
The incident-response variant, modelled on Kamiya et al.’s cyberattack study and Lending, Minnick, and Schorno’s data-breach work, tests whether firms with dedicated AI governance suffer smaller valuation losses when AI-related adverse events occur — a biased output, a regulatory inquiry, a high-profile deployment failure. This requires a database of AI-specific incidents matched to governance classifications. As of 2026, no such database exists, though the increasing frequency of AI-related controversies and the emerging EU AI Act enforcement actions will eventually provide the event population.
Governance Quality Scoring
Move beyond the binary classified/unclassified distinction. Weight HPE’s four-body architecture differently from a single Technology Committee reference. Weight named policies differently from implied ones.
The lesson from Bebchuk, Cohen, and Ferrell (2009) is that governance features are not equally important — of Gompers et al.’s twenty-four provisions, only six drove the return association — and the lesson from Adams and Ferreira (2009) is that the same governance feature can have positive or negative effects depending on the firm’s context. Cohen, Dey, and Lys (”Real and Accrual-Based Earnings Management in the Pre- and Post-Sarbanes-Oxley Periods”, *The Accounting Review*, 2008) showed that governance effects are detectable only when the measurement instrument is granular enough to capture meaningful variation — aggregate indices mask the signal.
For AI governance specifically, a proper scoring system would need to distinguish between at least:
*Structural depth:* A named Responsible AI Committee with a disclosed charter versus AI mentioned within an existing Technology Committee’s mandate.
*Skills integration:* AI/ML expertise listed in the director skills matrix versus no board-level technical qualification.
*Policy specificity:* A named AI ethics policy or AI risk framework referenced in the proxy versus general technology risk language.
*Reporting frequency:* How often the AI governance body reports to the full board — quarterly, annually, or not disclosed.
*Management integration:* Whether the C-suite includes a Chief AI Officer or equivalent, creating organisational accountability below the board level.
None of these distinctions are captured by our current three-tier classification, and most cannot be reliably extracted from proxy filings through automated text analysis alone. They would require manual expert coding of each filing — expensive, but necessary if the measurement instrument is to have enough resolution to detect a signal.
Causal Identification
The deepest methodological challenge in governance-return research is endogeneity: companies that adopt governance innovations are systematically different from companies that do not, in ways that affect returns independently of the governance decision itself. Adams and Ferreira addressed this with instrumental variables. Gompers et al. relied on the argument that anti-takeover provisions were stable over time (governance as a “quasi-fixed” characteristic). The ESG literature has never fully resolved the problem, which is why the Friede et al. meta-analysis, despite its 2,200 studies, remains contested.
For AI governance, three causal identification strategies are plausible in the medium term:
Difference-in-differences. Compare return trajectories of firms that *adopt* AI governance infrastructure (move from Unconnected or Routed to Governed between proxy seasons) to those that do not. This requires at least two consecutive proxy seasons with comparable governance classifications — achievable by 2027 if the classification methodology is held constant. The identifying assumption is that, absent the governance adoption, the adopters’ returns would have followed the same trajectory as non-adopters’. The methodological template is Bertrand and Mullainathan’s study of business combination laws (”Enjoying the Quiet Life? Corporate Governance and Managerial Preferences”, *Journal of Political Economy*, 2003), which used staggered state-level anti-takeover statute adoption as a natural experiment to identify governance effects on firm behaviour — the closest corporate-finance precedent for a governance-adoption DiD design.
Propensity score matching. Match each governed company to a control company with similar size, sector, profitability, and prior return trajectory but no AI governance infrastructure. This isolates the governance variable from the observable characteristics that co-determine both governance adoption and returns. The method requires enough governed companies to form a treatment group and enough ungoverned companies with similar observable characteristics to form a matched control group. At sixty-two companies, with fifteen governed, the overlap region is too thin. At several hundred, it becomes feasible.
Regulatory or advisory-firm shocks. If ISS or Glass Lewis introduces an AI governance voting policy — screening for AI committee disclosure or recommending against audit committee chairs at AI-heavy companies without dedicated AI oversight — the announcement creates an exogenous shock. Firms that already have the infrastructure are unaffected; firms that do not face sudden pressure to adopt. The differential market response measures the value the market assigns to AI governance infrastructure specifically, not to the unobservable firm-quality characteristics that correlate with early adoption.
Industry-Matched and Factor-Controlled Returns
Compare each governed company to a size-and-industry-matched peer, not to the full sample. The sector concentration of the governed tier (60% technology) makes any unmatched comparison a sector bet. Beyond matching, isolate the governance variable from momentum, value, profitability, and sector factors using a standard asset-pricing framework. Fama and French showed decades ago that uncontrolled return comparisons are unreliable — any governance factor test needs to operate within at minimum a four- or five-factor model.
The proper analytical unit is the *alpha* — the residual return after accounting for market, size, value, profitability, and momentum exposures — not the raw return. Our test uses raw returns. A proper test would regress each firm’s monthly return series on the Fama-French-Carhart factors and test whether the estimated alpha differs systematically between governance tiers. This requires at least twenty-four months of return data per firm to estimate the factor loadings with reasonable precision.
The Timeline
None of these requirements are exotic. They are the standard methodological apparatus of empirical corporate finance. But taken together, they impose a clear timeline: a minimally credible event-study test requires peak-season 2026 data (available by mid-2026), a difference-in-differences test requires the 2027 proxy season for comparison, and a properly powered cross-sectional test with factor controls requires at least 2027–2028 data with twenty-four months of post-classification returns.
What makes AI governance research difficult is not the statistics — it is the data. Twenty-one percent of sixty-two early-season filers have dedicated AI governance infrastructure. A proper test needs that number to be several hundred, and it needs at least two years of comparable data. The cybersecurity governance literature required a decade between the first committee-level disclosures and the first reliable empirical studies. AI governance is moving faster, but the methodological bar is the same. We are in the data-collection phase. The test-design phase is next. The results phase is, at the earliest, 2027.
What This Means Now
The absence of a measurable premium is itself a finding. It says that the market, as of February 2026, does not systematically distinguish between companies that have built AI governance infrastructure and companies that have not. Three interpretations are possible, and each carries different implications for investors, corporate secretaries, and proxy advisory firms.
The market does not care — yet. AI governance disclosure is too new, too sparse, and too heterogeneous for investors to price. This is consistent with the early-phase pattern in Gompers et al.: governance features predicted returns *before* governance screening became common, precisely because the market had not yet priced them. If this interpretation is correct, the absence of a premium today is what creates the opportunity for one tomorrow. The companies building AI governance infrastructure now are doing so ahead of investor demand, ahead of advisory-firm screening, and ahead of index-provider coverage. If AI governance follows the trajectory of anti-takeover provisions, board diversity, or ESG, the returns to early adoption will accrue before standardised measurement frameworks make the governance variable visible — and will attenuate once they do. The investment implication is a timing question: when does the market begin to price AI governance, and are the current early adopters the ones that will benefit?
The market cannot see it. If seventy-nine percent of AI-mentioning companies do not disclose dedicated governance infrastructure, and the twenty-one percent that do are not uniformly classified by any index provider or advisory firm, then investors have no systematic way to act on the information even if they wanted to. The signal exists in scattered proxy filings. No aggregator has made it investable. This is a visibility problem, not a value problem. The practical implication is that the infrastructure gap documented in the earlier articles in this series — the disconnect between what companies are doing internally on AI governance and what they disclose in the proxy — is not just a governance gap but a market-information gap. Companies with genuine AI governance infrastructure that do not disclose it clearly are leaving potential valuation on the table. Companies that disclose governance language without substance are creating noise that degrades the signal for everyone. The disclosure quality question, in other words, is upstream of the return question.
Governance does not create value at the infrastructure level. This is the most consequential interpretation and the least explored in the governance literature. The features we measure — committee names, policy references, skills-matrix entries — are *structural* features. They describe the existence of governance bodies, not the quality of governance decisions. A Responsible AI Committee that meets quarterly and reviews every high-risk AI deployment is a fundamentally different thing from a Responsible AI Committee that was created for the proxy filing and has met once.
The distinction matters because the governance-return literature has generally treated governance as a structural variable — does the board have this feature or not? — and has found diminishing returns to that approach over two decades. The deeper question is whether AI governance creates value through the *decisions* the governance body makes: which AI applications to deploy, which to reject, what risk thresholds to set, how to respond when a model produces biased outputs, when to slow a deployment that engineering wants to ship. These are operational decisions with direct financial consequences. A company that catches a biased hiring algorithm before it creates legal liability has received measurable value from its AI governance infrastructure. A company whose AI risk committee identifies a regulatory exposure before the EU AI Act enforcement action arrives has received measurable value. But none of this shows up in a cross-sectional return comparison, because the value is event-specific, decision-specific, and largely invisible from outside the organisation.
This is the same distinction that the cybersecurity governance literature eventually found: governance infrastructure did not predict cross-sectional returns, but it predicted smaller losses when adverse events occurred. The value was in the tail-risk protection, not in the baseline performance. If AI governance follows the same pattern, its value will be measurable not by comparing governed firms to ungoverned firms over rolling periods, but by comparing how governed and ungoverned firms respond when things go wrong — a biased output, a regulatory inquiry, a high-profile deployment failure, a copyright infringement claim. That test requires a database of AI-related adverse events matched to governance classifications. It does not exist today. It will exist within a few years, as AI-related controversies accumulate and the EU AI Act’s enforcement mechanism generates a record of regulatory actions.
The honest answer is that forty-six companies and twelve months of returns cannot distinguish between these three interpretations — and at this stage in the field’s development, they should not be expected to. What this test establishes is a first baseline: a set of numbers that will gain meaning only when measured again, with more companies, across more seasons. Anyone making investment decisions based on AI governance disclosure today is acting on conviction, not evidence. That may turn out to be right — early-phase governance factors have rewarded early movers before — but the data to support the claim does not yet exist.
The numbers will update as the sample expands. If the six-month gradient persists in the peak-season universe, the event-study case strengthens. If it flattens, the null result holds.
Tanya Matanda is a governance strategist bridging institutional oversight, AI governance, and fiduciary resilience. Her work supports boards, LPs, and regulators in designing governance systems fit for the AI era.
Copyright © 2025 Matanda Advisory Services
Research and Audio Supported by AI Systems
Methodology and references available on request.